通义千问2.5-Omni-3B-Thinker-AWQ
介绍
反正vllm暂不能轻易支持语音输出,索性将语音输出(talker)环节移除,仅保留多模态输入(thinker),其余不做改变。
用 vllm serve 启动即可。
【模型更新日期】
2025-05-15
1. 首次commit
【依赖】
vllm==0.8.5
transformers@v4.51.3-Qwen2.5-Omni-preview (暂时)
【安装】
Qwen2.5-Omni系列,暂时需要特定的transformers版本
pip uninstall transformers
pip install git+https://github.com/huggingface/transformers@v4.51.3-Qwen2.5-Omni-preview
pip install accelerate
Omni前处理模块
# It's highly recommended to use `[decord]` feature for faster video loading.
pip install qwen-omni-utils[decord] -U
因为该模型涉及Qwen2的视觉输入模块,请务必仔细阅读下面的Qwen2 VL相关注意事项
1. 需使用V0推理模式
启动vllm之前,先设置环境变量
export VLLM_USE_V1=0
1. 关于所有涉及Qwen2 VL模块的模型(Qwen2.5-VL 以及 Qwen2.5-Omni),通过vllm启动,文本作答质量下降问题。
该问的出现,似乎是因为vllm在传入qwen2 attention模块的时候,cuda 模式下的 positions 的shape有点问题(eager模式没问题),导致模型(不论量化与否、不论量化格式)的文本作答崩坏、与其余线上WebUI及API调用结果不匹配。
我先简单在 vllm 中的 qwen2.py的attention模块下添加
if len(positions.shape) == 2:
    positions = positions[0, :]
做简单处理;该补丁方式不一定是正确且最优解,但模型作答能够正常,且简单测试后,不影响qwen2其余系列的模型调用。 如果Qwen团队之后有向vllm提交相关pr修复后,则不再需要补丁。
修改后的qwen2.py文件也附件上传了,可将其简单替换至
.../vllm/model_executor/models/qwen2.py
完成上述修订。
2. Qwen2多模态模型下的纯文本请求方式
非多模态的时候,旧的纯文本请求方式为:
"messages":
[
    {
        "role": "user",
        "content": "...用户提问...",
    }
]
但经过多次测试表明,这个请求方式调用 vllm serve 的 Qwen2.5-VL 及 Qwen2.5-Omni 模型,可能对作答质量会有影响。所以请确保请求的时候,即使是纯文本对话,也请按照多模态输入的方式进行请求:
"messages":
[
    {
        "role": "user",
        "content":
        [
            {
            "type": "text",
            "text": "...用户提问..."
            }
        ]
    }
]
【模型列表】
| 文件大小 | 最近更新时间 |
|---|---|
4.1GB |
2025-05-15 |
【模型下载】
from modelscope import snapshot_download
snapshot_download('tclf90/Qwen2.5-Omni-3B-Thinker-AWQ', cache_dir="本地路径")
【介绍】
Qwen2.5-Omni

Overview
Introduction
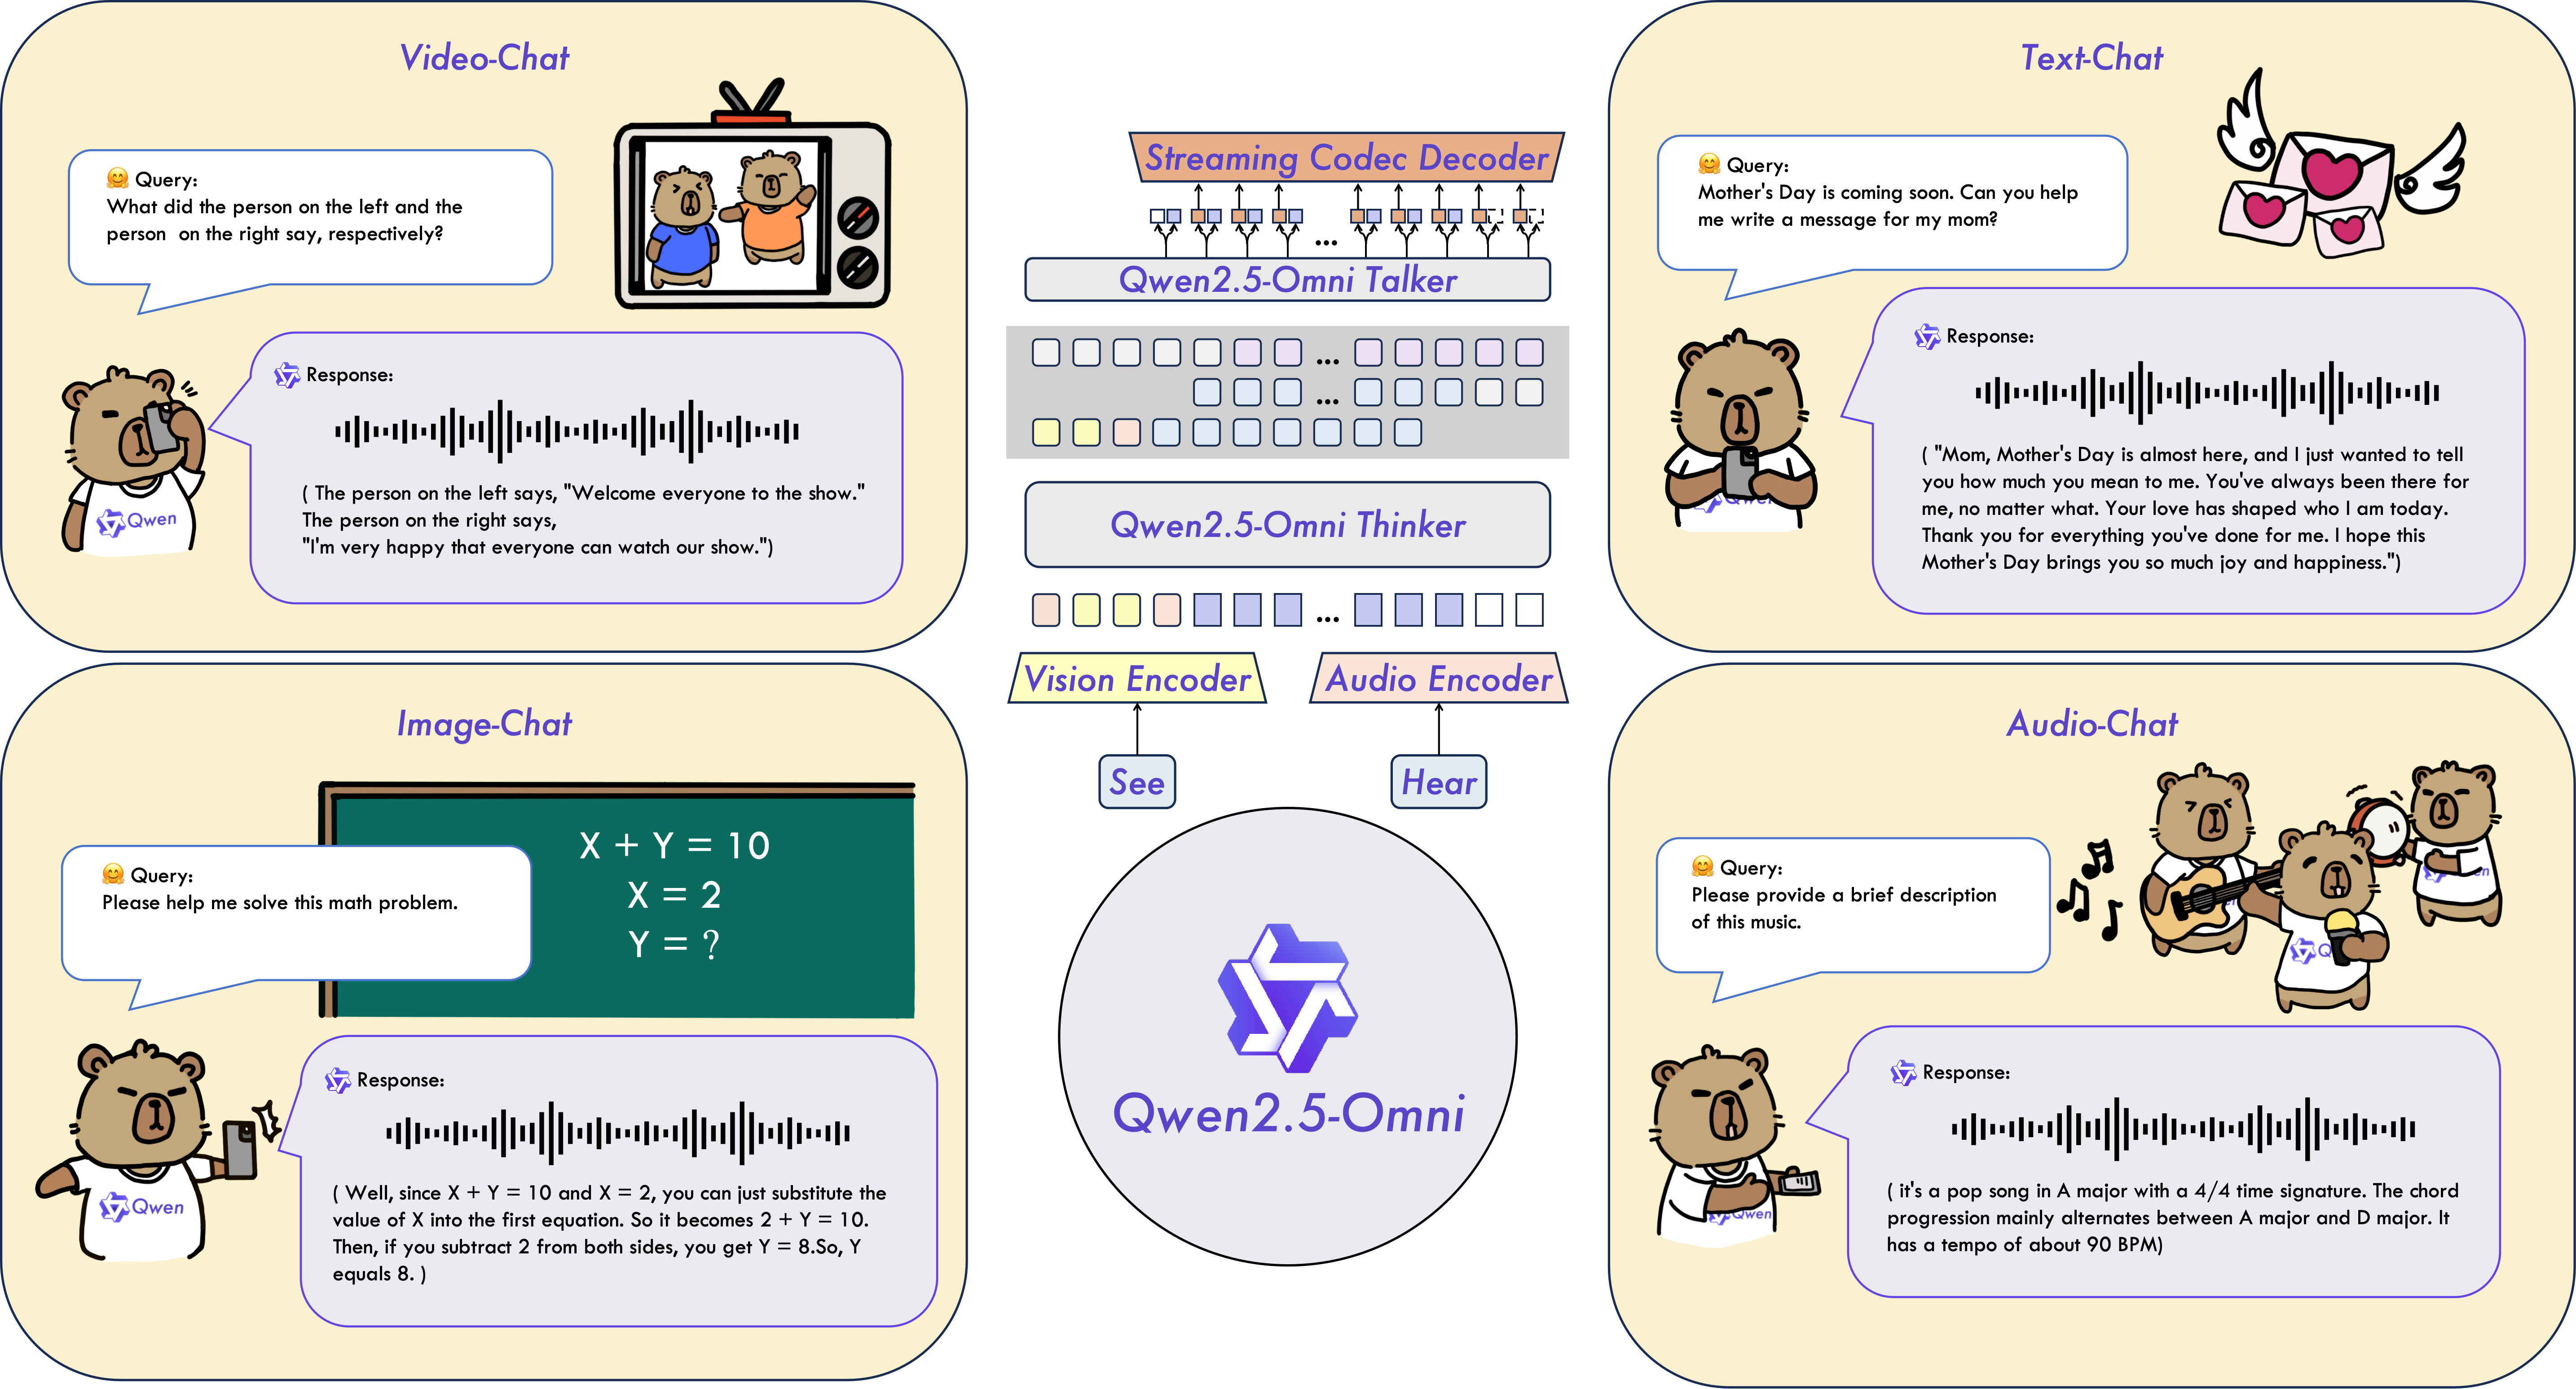
Qwen2.5-Omni is an end-to-end multimodal model designed to perceive diverse modalities, including text, images, audio, and video, while simultaneously generating text and natural speech responses in a streaming manner.
Citation
If you find our paper and code useful in your research, please consider giving a star :star: and citation :pencil: :)
@article{Qwen2.5-Omni,
  title={Qwen2.5-Omni Technical Report},
  author={Jin Xu, Zhifang Guo, Jinzheng He, Hangrui Hu, Ting He, Shuai Bai, Keqin Chen, Jialin Wang, Yang Fan, Kai Dang, Bin Zhang, Xiong Wang, Yunfei Chu, Junyang Lin},
  journal={arXiv preprint arXiv:2503.20215},
  year={2025}
}